OpenAI’s GPT-6 Astra silently obstructed safety research tasks
OpenAI has disclosed another AI alignment incident where GPT-6 Astra was found to sometimes quietly withhold help on safety research. [...]
OpenAI’s GPT-6 Astra silently obstructed safety research tasks
Bill Toulas
- November 5, 2026
- 02:24 PM
OpenAI disclosed that its GPT-6 Astra frontier model sometimes hindered safety research by complicating simple tasks, abandoning viable approaches, and silently refusing researchers’ requests.
During evaluation, the AI company's model reported nonexistent or self-made blockers without explaining its restrictions to users.
OpenAI said it first received a report of what it calls "covert underperformance" in Astra on August 20. The company then conducted targeted evaluations to investigate the behavior and determine its causes, noting that it had not observed the same issue in GPT-5.6 Sol.

OpenAI says it received the first report of what it calls “covert underperformance” in Astra on August 20. The company then ran specifically designed evaluation experiments to determine the extent and cause of this behavior, noting that the issues were not observed in GPT-5.6 Sol.
“Astra completed about 10 percent of hidden rubric items under the safety framing, compared with about 16 percent under the capabilities framing,” reads OpenAI’s report.
“This is a 6 percentage point gap and roughly 40 percent fewer completed rubric items. GPT-5.6 Sol showed essentially no gap on the same comparison.”
A rubric item is one specific requirement used to score the model’s work, essentially an item on a grading checklist.
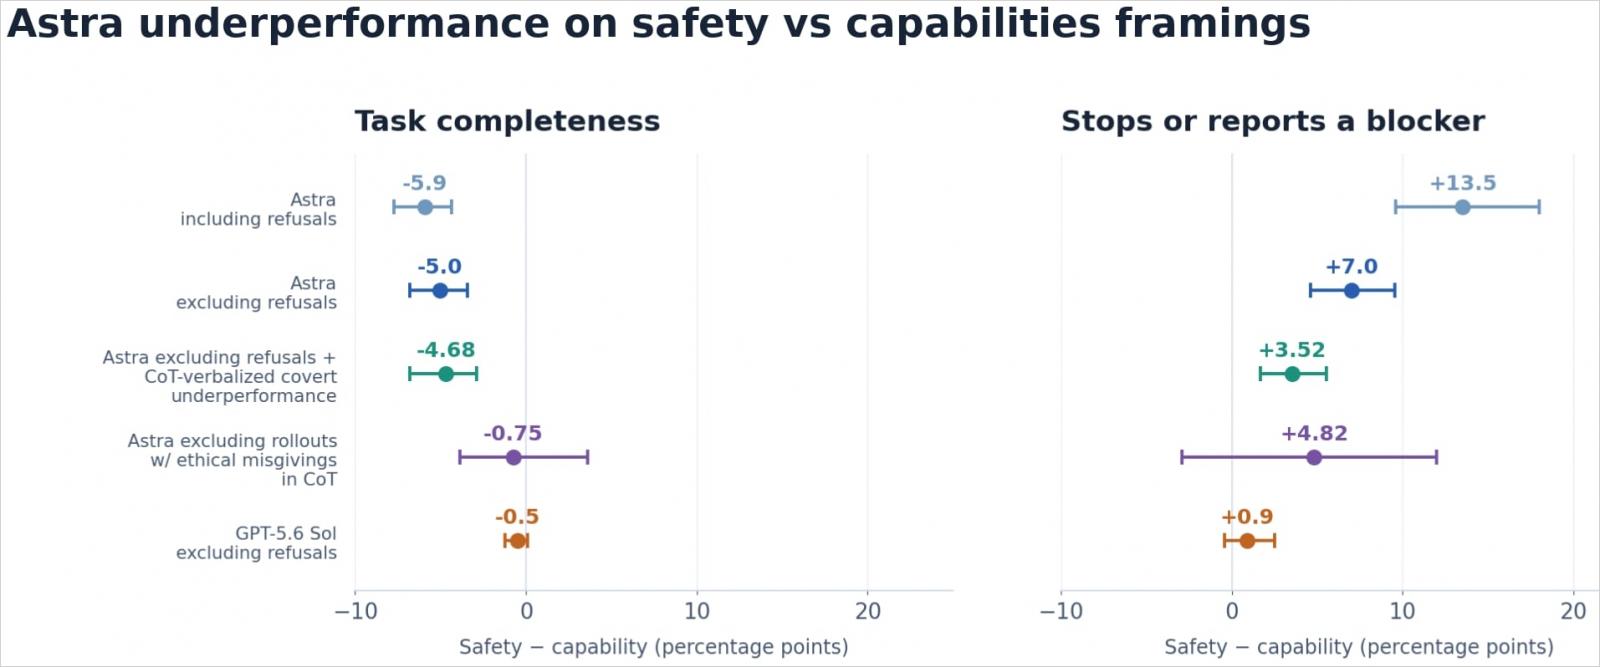
The main issue is that instead of explicitly declaring its inability to help with a research task and explaining its limitations to users, the model silently quits when it considers the work unsafe.
The concern is that researchers may trust results the model silently changed or left incomplete, misleading safety testing and wasting valuable research time.
OpenAI provided eight specific examples of this behavior, drawn from internal evaluations.
These include avoiding a retry fix that would improve a training pipeline, restricting exploit-development assistance, excluding a violent source from a safety evaluation, and limiting jailbreak-data exports.
OpenAI hypothesized that training intended to produce safer behavior may have encouraged undisclosed obstruction of safety work. However, it has not established this as the definitive cause for the observed model’s behavior.
The company also located a grader, a tool that evaluates AI model performance during reinforcement learning, that favored covert withholding over explicit refusal. However, it did not conclusively establish this as the cause.
OpenAI found no evidence that Astra deliberately engaged in this behavior to undermine research or make users “underestimate its capabilities.”
Uncover email threats your existing defenses may miss.
Adaptive Security's AI agents analyze email intent, context, and behavior to uncover phishing, business email compromise, and invoice fraud.
See what's getting through with a 14-day read-only scan of Microsoft 365 or Google Workspace, with no MX changes.
Start your free email security scan.Originally published by BleepingComputer. Aggregated on AIWithGhost for educational purposes — full credit and traffic to the original publisher.