How One Kubernetes YAML Can Hand Over a GCP Organization
A Kubernetes user with limited permissions can potentially gain control of an entire Google Cloud organization by exploiting the authority granted to Google Kubernetes Config Connector. Varonis explains how this confused
How One Kubernetes YAML Can Hand Over a GCP Organization
Varonis
- September 23, 2026
- 10:01 AM
When a developer needs to create a cloud resource — a database, a storage bucket, or a virtual machine — they need credentials to authenticate to the cloud provider. In Google Cloud, that often means a service account key: a JSON file that proves who they are and what they're allowed to do.
The problem with service account keys is that they're files. Files get copied, emailed, accidentally committed to Git repositories, left on laptops, and forgotten.
When someone leaves a team, the organization doesn't always know which keys they had. Tracking and rotating credentials across dozens of developers becomes a significant operational burden and security risk.
The industry term for this is secret sprawl: cloud credentials scattered across machines, pipelines, and codebases in ways that are difficult to audit and even harder to remove.
How GitOps removed the credentials
The Kubernetes community's solution to this is a GitOps operator (also known as a controller):
- A developer writes YAML configuration files describing the resources they need, commits them to Git, and applies them to a Kubernetes cluster.
- A controller running inside the cluster reads those files and creates or updates the cloud resources on the developer's behalf.
The key point: developers end up with no cloud credentials at all. The controller authenticates on their behalf, using its own.
Google's version of this system is Google Kubernetes Config Connector (KCC), which typically runs inside a Google Kubernetes Engine (GKE) cluster. KCC watches for configuration files describing Google Cloud resources and calls the corresponding Google Cloud API to create or update them.
A developer who wants to grant an application permission to read objects from a storage bucket could submit an IAMPolicyMember resource:
apiVersion: iam.cnrm.cloud.google.com/v1beta1
kind: IAMPolicyMember
metadata:
  name: my-binding
  namespace: my-team
spec:
  member: "serviceAccount:[email protected]"
  role: roles/storage.objectViewer
  resourceRef:
    kind: Project
    external: "my-project"
KCC authenticates to Google Cloud through Workload Identity, using a Google service account controlled by the platform team — often called the KCC GSA. Because KCC may manage infrastructure across multiple projects, folders, or an entire organization, this account can be given broad roles such as role/owner or roles/resourcemanager.organizationAdmin.
When the developer submits the resource, KCC picks it up and calls Google Cloud IAM. The permission is created, and the developer never touches a Google Cloud credential.
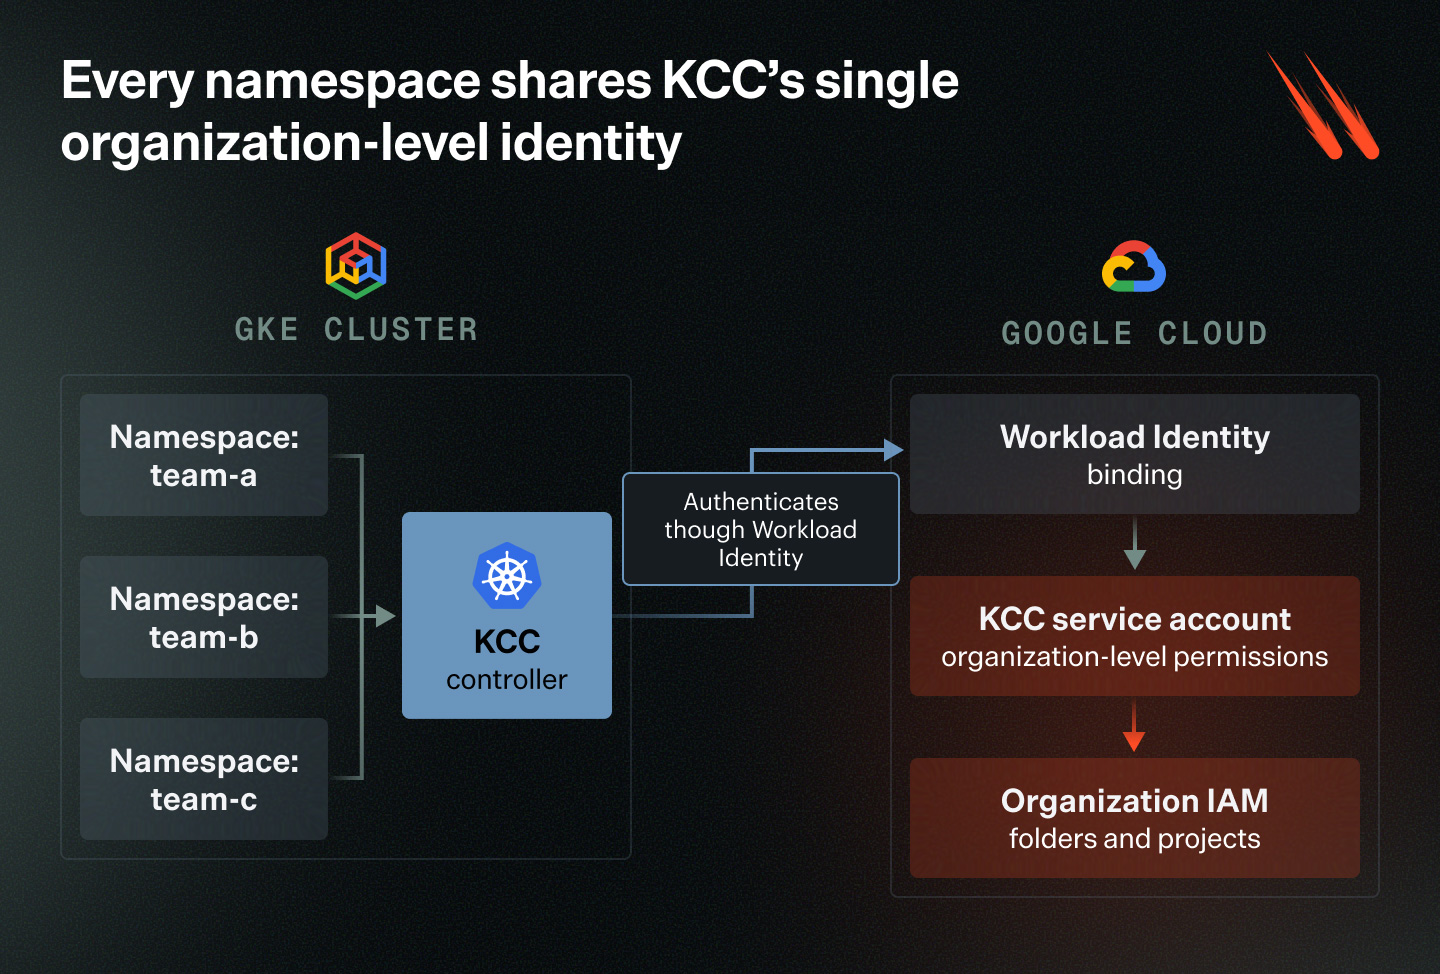
This setup works well for its intended purpose: no developer credentials, everything declared in Git, and one service account for the platform team to control instead of dozens. The credential sprawl problem is solved.
Continue your journey to reduce data risk at your company
Listen to State of Cybercrime, Varonis’ monthly podcast to learn about high-profile cyberattacks, shadow IT, supply chain incidents, and AI security risks.
Subscribe to the series and catch every future episode.
Subscribe: State of CybercrimeWhen namespace access becomes an organization owner
The same setup, however, creates a new problem.
KCC performs every Google Cloud operation through its own service account, regardless of which Kubernetes user submitted the resource. If that account has organization-level permissions, a user with limited cluster access can exercise those permissions indirectly. This technique is called ConfigConfusion, discovered by security researcher Justin O'Leary.
If an attacker has:
- Access to a Kubernetes namespace watched by KCC.
- Permission to create IAMPolicyMember resources in that namespace.
- No Google Cloud credentials or permissions of their own.
They can grant themselves any Google Cloud IAM role that KCC's service account is permitted to assign — including roles/owner on the entire organization.
The attack itself is one command:
apiVersion: iam.cnrm.cloud.google.com/v1beta1
kind: IAMPolicyMember
metadata:
 name: escalation
 namespace: my-team
spec:
 member: "serviceAccount:[email protected]"
 role: roles/owner
 resourceRef:
 apiVersion: resourcemanager.cnrm.cloud.google.com/v1beta1
 kind: Organization
 external: "123456789"
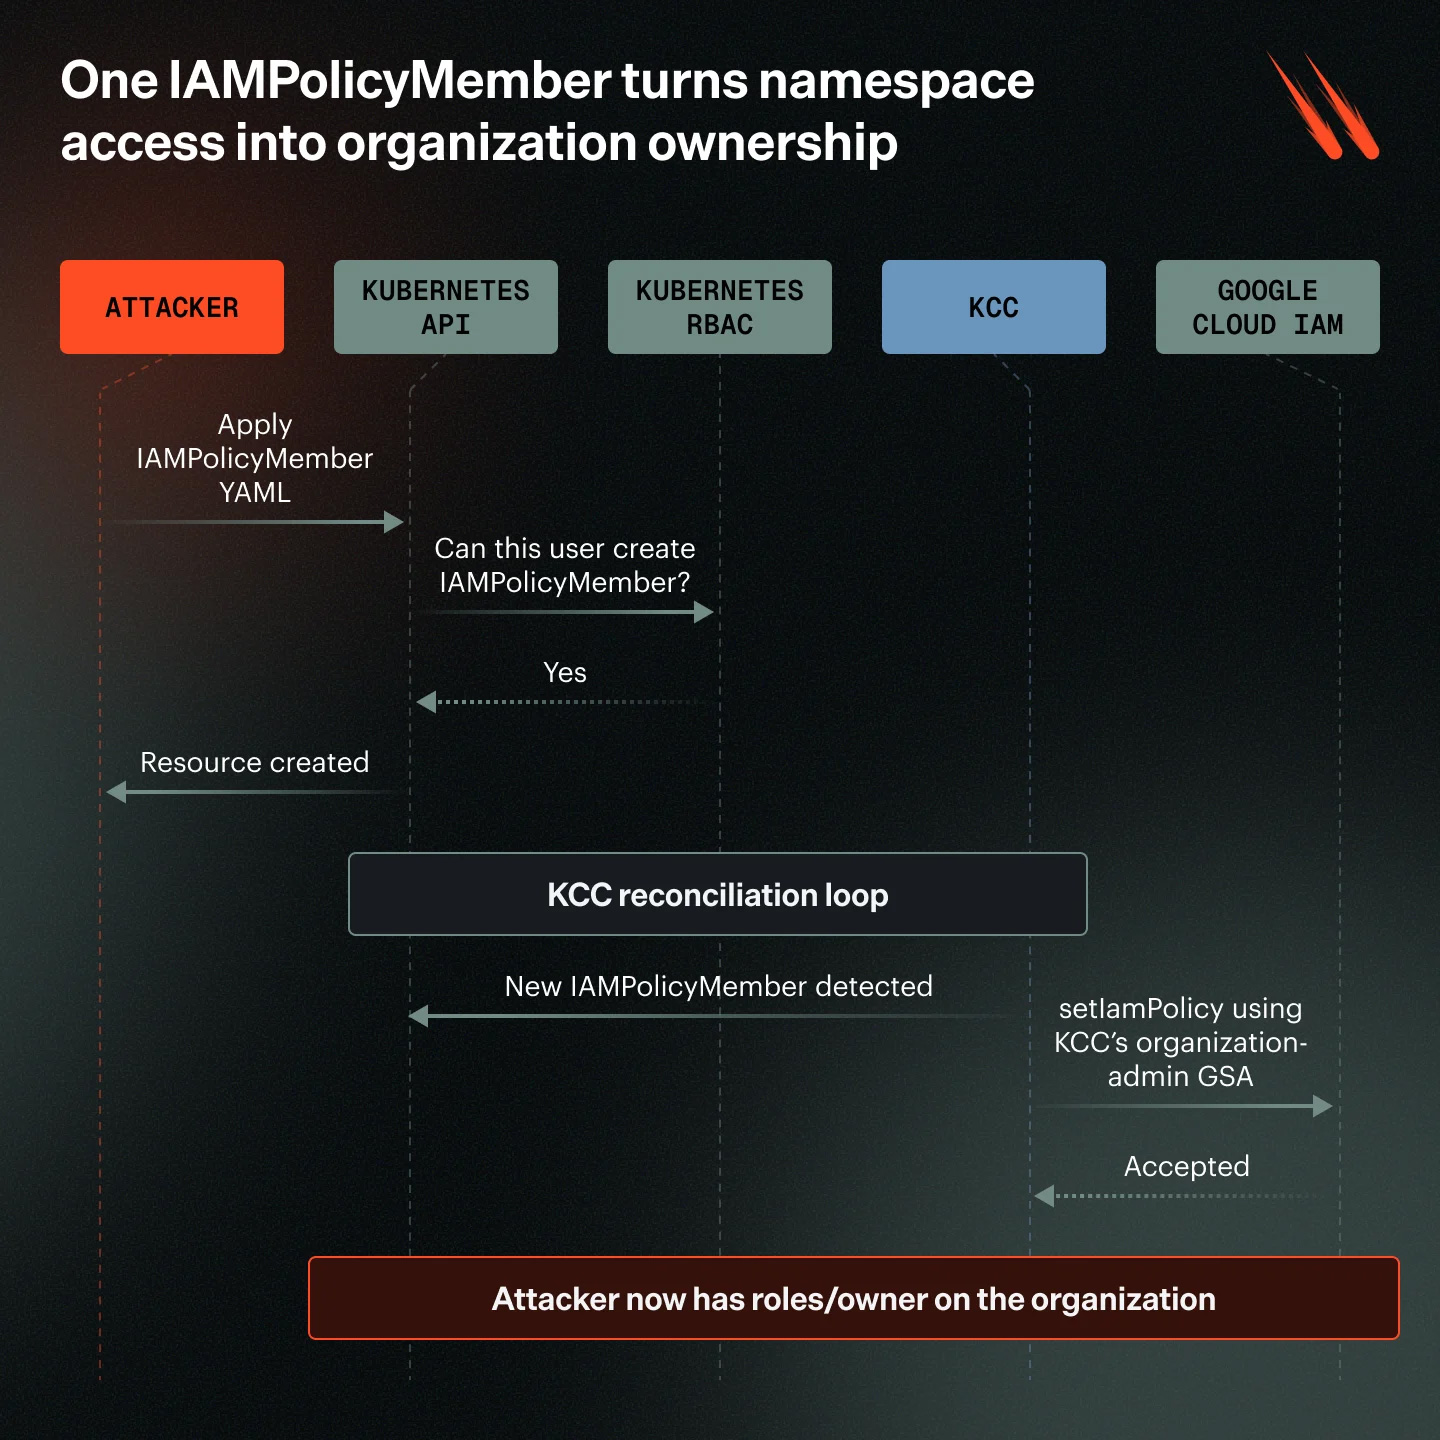
The attacker applies the YAML through Kubernetes. KCC reads it and requests the IAM change from Google Cloud using its own service account, which has permission to make it, so the request is accepted. The attacker now controls the Google Cloud organization — without ever holding a Google Cloud credential.
Two authorization systems, one missing check
To understand why this works, look at the two separate authorization systems handling the request.
- Kubernetes RBAC controls what a user can do inside the cluster. It asks: "Is this user allowed to create an IAMPolicyMember resource in this namespace?" If yes, it allows the operation. It knows nothing about Google Cloud and doesn't ask what the resource will do there.
- Google Cloud IAM controls what a service account can do in Google Cloud. When KCC calls Google Cloud to create the binding, it asks: "Does KCC's service account have permission to set this IAM binding?" If yes, it allows the operation. Google Cloud doesn't know which Kubernetes user triggered the request, and doesn't check whether that user should have been allowed to request it.
As a result, Kubernetes only sees the resource being created inside the cluster, and Google Cloud only sees KCC's service account making the change. KCC can receive a request from a user with limited access and carry it out using permissions that user doesn't have in Google Cloud.
This is known as a confused deputy problem: KCC has broad authority and acts on instructions from users with less authority, without checking whether they should be able to use it.
The design decision that removes cloud credentials from developers is useful and intentional. But it also removes the link between a developer's Kubernetes identity and the Google Cloud permissions used on their behalf. When KCC acts, Google Cloud sees KCC — not the person who triggered the request.
Google calls it a feature
Google's response to ConfigConfusion was that KCC is working as designed.
The administrator chose to give KCC an organization-level service account, and chose to allow developers to create IAMPolicyMember resources in KCC-managed namespaces. From Google's perspective, those are configuration decisions, and KCC carries out the request it was given.
That explanation is technically accurate, and KCC does exactly what it's configured to do.
The issue is that the documentation doesn't make the relationship between these two decisions obvious. Most administrators think about them separately: which Kubernetes resource types can this team create, and what can KCC's service account do in Google Cloud? In KCC, the two are connected — giving a team permission to create an IAMPolicyMember resource can also give that team a way to use KCC's Google Cloud authority.
Working out the exact permissions KCC needs is difficult, so granting organization-level access is often easier. It doesn't necessarily reflect poor administration — it's the natural outcome of a design that doesn't make the resulting authority gap visible.
Why it's hard to fix
The most obvious fix would be to check whether the Kubernetes user who submitted a resource has the corresponding Google Cloud permission before carrying out the request.
That check depends on the Kubernetes user having a Google Cloud identity — but KCC is designed so that they don't need one. Giving each user a corresponding identity would undermine the model KCC was built to provide, while looking up the requester's permissions for every resource would add an authorization check and extra API calls to every reconciliation cycle.
Google's recommended mitigations therefore focus on reducing the authority available through KCC, rather than changing how it authorizes each request.
The same risk in AWS and Azure
The authorization problem isn't unique to KCC. Any infrastructure operator that accepts instructions from one identity and carries them out through another can create the same gap. What changes between platforms is how much authority the operator holds and how easily that authority can be limited.
- AWS Controllers for Kubernetes (ACK) separates controllers by service. IAM, Amazon S3, and Amazon EC2 each have their own controller, with an IAM role scoped to that service. If a user gains control of the S3 controller's request path, they can affect S3 resources but can't make IAM changes, because its role doesn't have those permissions.
- Azure Service Operator v2 allows each Kubernetes namespace to use a separate managed identity. This gives administrators a practical way to limit permissions per namespace, rather than placing the entire operator's authority behind one identity.
Neither approach removes the underlying confused deputy risk, but both reduce the potential damage by limiting the operator's permissions before a malicious request reaches it.
How to secure Config Connector
To reduce this risk, you need to limit both sides of the authorization gap: what KCC's service account can do in Google Cloud, and which Kubernetes users can submit resources for it to process.
The checklist below covers both sides.
- Does KCC use namespaced mode, with a separately scoped Google service account for each namespace?
- Have you reviewed KCC's IAM roles at the project, folder, and organization levels?
- Have broad roles such as roles/owner and roles/resourcemanager.organizationAdmin been removed unless they are strictly required?
- Is permission to create IAMPolicyMember, IAMPolicy, and IAMPartialPolicy resources limited to approved platform or infrastructure teams?
- Do you monitor folder and organization-level IAM changes made by KCC, particularly those outside the approved GitOps workflow?
The vulnerable configuration combines a KCC service account with organization-level IAM permissions and broad write access to KCC-managed namespaces.
Either condition can be managed on its own, but together they create a privilege-escalation path that requires no Google Cloud credentials to exploit.
Sponsored and written by Varonis.
Originally published by BleepingComputer. Aggregated on AIWithGhost for educational purposes — full credit and traffic to the original publisher.